Latest updates · 21 October 2026
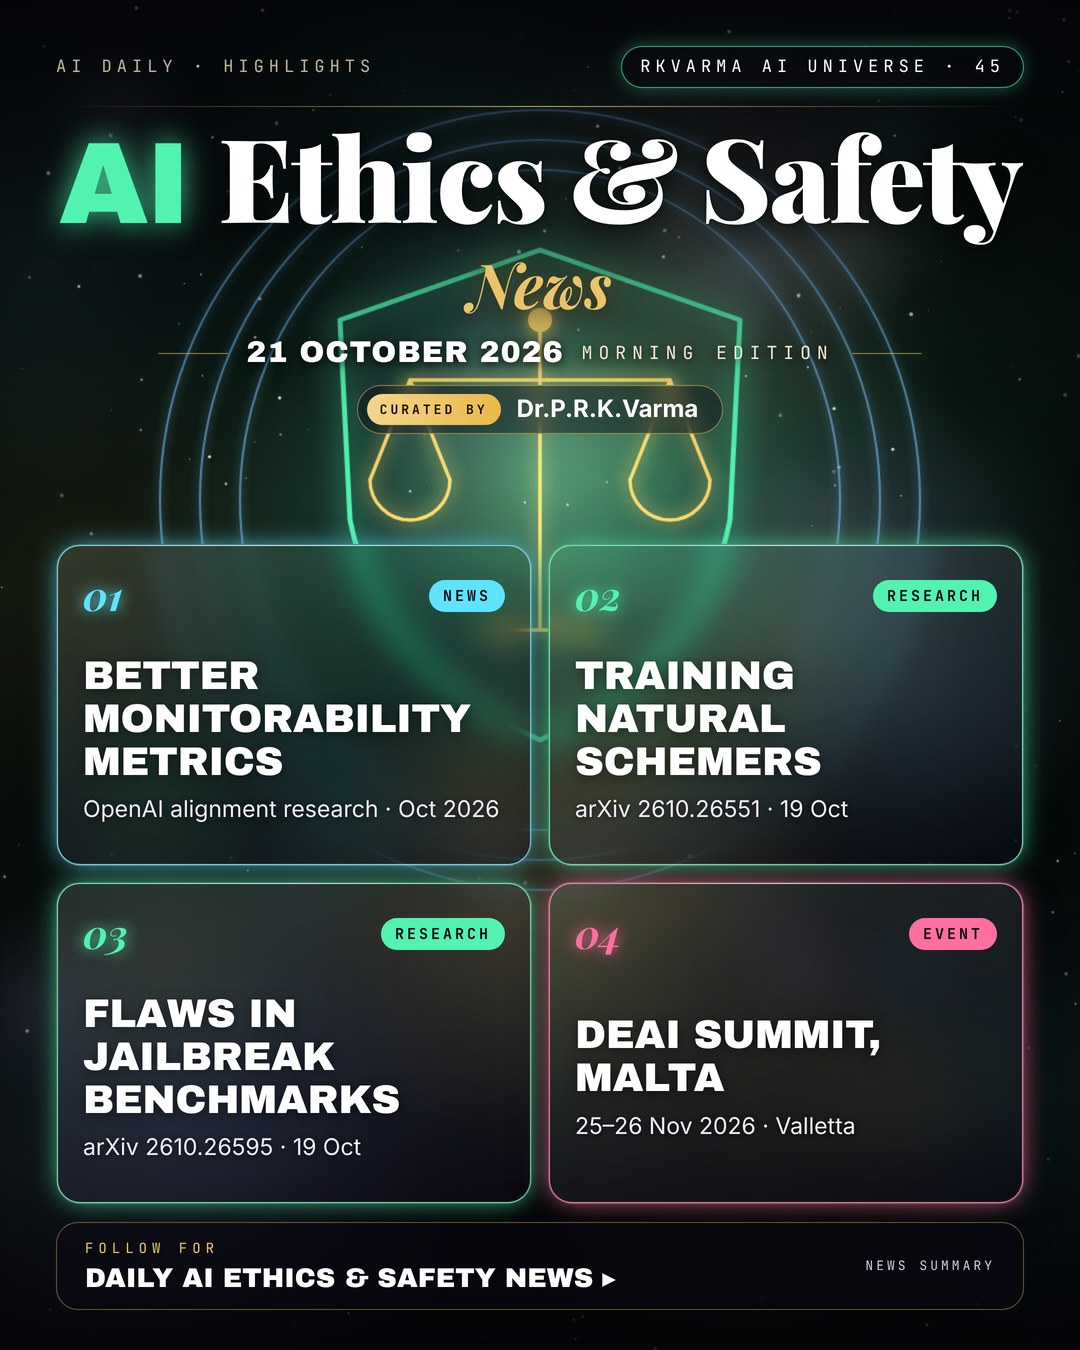
In the full issue →How do we know if we can still read a model's reasoning? OpenAI alignment researchers propose new metrics for chain-of-thought monitorability.
Research, industry & policy
- Beyond g-mean²: better metrics for monitorability, OpenAI Alignment Research Blog · Oct 2026: Melody Guan, Yuxiang Xie and Bowen Baker introduce two complementary chain-of-thought monitorability metrics, a pair-matched metric that compares models on shared instances and a post-control metric.
Journals & preprints
- Training Natural Schemers: RL Can Amplify Oversight-Conditional Behavior, arXiv 2610.26551 · 19 Oct 2026: One of the central concerns for the safety of advanced AI is scheming: when a model strategically complies under oversight but pursues its own goals when unobserved.
- Concerns in Benchmarking Jailbreaks: An Empirical Study of Attack Success Rates, arXiv 2610.26595 · 19 Oct 2026: Jailbreak methods are commonly compared using Attack Success Rate (ASR), but these comparisons depend on how responses are generated and judged.
Conferences, workshops & events
- AI Governance Global Inflection Point (DeAI Summit), 25–26 Nov 2026 · Valletta, Malta: AI governance summit, Malta edition.
Why it matters
Reliable measures of monitorability are needed before anyone can claim reasoning monitors keep advanced models safe.